Monkey Testing vs. Gorilla Testing (2026)
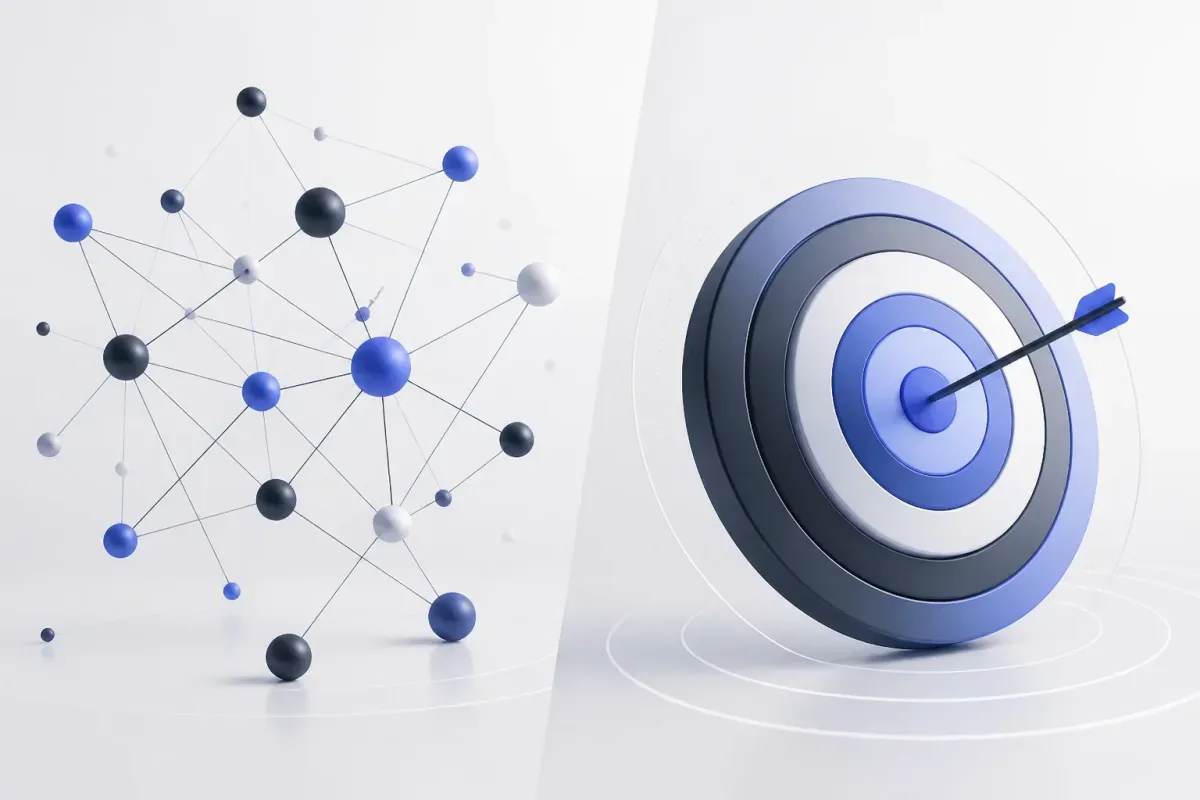
A release candidate can look fine along its happy path, then fail after rapid navigation, unusual input, or repeated use of one newly changed feature. When that happens, choosing a test technique is really a choice about the question you need answered: “Where might this app fail?” or “How hard can this feature be pushed?”
The short answer: use monkey testing to explore broad, unexpected failure states with random or pseudo-random interactions. Use gorilla testing to apply sustained, focused pressure to one selected feature or module. Neither technique replaces the other. Monkey testing gives you breadth; gorilla testing gives you depth.
Monkey testing vs. gorilla testing at a glance
The comparison below reflects published Android Monkey research and practitioner descriptions of gorilla testing. It is a decision guide, not evidence that either method has a universally higher defect-finding rate.
Dimension | Monkey testing | Gorilla testing |
Scope | Broad exploration across an application | One chosen feature, module, or risk area |
Input pattern | Random or pseudo-random interactions | Repeated interactions within a selected target; inputs can be structured, varied, or random |
Primary question | What unexpected states or robustness failures can surface? | How does this high-risk area behave under concentrated pressure? |
Preparation | Lower up-front targeting, followed by triage and reproduction work | Deliberate target selection, observation, repeat cycles, and follow-up |
Main strength | Breadth across unfamiliar paths and states | Depth in a critical or recently changed area |
Main limitation | A detected crash may be difficult to reproduce | Defects outside the chosen area can remain unseen |
Best fit | Early robustness exploration and unknown-risk discovery | Investigation of a business-critical, fragile, or recently changed feature |
Get the Mobile Testing Playbook Used by 800+ QA Teams
Discover 50+ battle-tested strategies to catch critical bugs before production and ship 5-star apps faster.
What is monkey testing?
Monkey testing is a testing approach that uses random or pseudo-random inputs to explore software behavior outside a prewritten happy path. A historical software-testing text describes a test monkey as an automation tool intended to simulate actions users might take; that explains the term, but it is not current operating guidance for any platform. Lessons Learned in Software Testing
The value is not randomness for its own sake. Random interaction can move an app through awkward sequences that a carefully scripted test may never try: returning to a screen repeatedly, switching paths at an unexpected moment, or acting before the app has settled into the state you expected. Those paths can expose crashes, stuck states, and robustness problems that deserve investigation.
For Android, Android Monkey is the best-known example of this style of random stress testing. It is important to separate the general technique from the Android-specific tool: monkey testing can describe a broad approach, while the research figures in this article concern the Android tool and the study populations named alongside them.
What Android Monkey research actually shows
The strongest published evidence in this comparison concerns Android Monkey rather than monkey testing across every platform. In a 2018 study of random testing for Android, researchers reported that Monkey runs averaged 85 seconds, crashed 15 widely used apps, and achieved coverage only 2–3% lower than manual exploration across 62 apps. The study does not identify the exact coverage granularity for that 2–3% comparison, so it should be read as the study’s coverage measure rather than as a claim about a particular code-coverage metric. Patel, Srinivasan, Rahaman, and Neamtiu’s study
The same 2018 study found that changing Monkey’s default event distribution was unlikely to improve coverage except in isolated cases. That finding is useful if you are deciding whether to start with a broad automated exploration pass, but it is not a promise about the runtime, crash rate, or coverage of your current app.
A crash is not yet a reproducible defect
A generated crash can be valuable evidence, but it is not automatically ready for a bug tracker. A 2023 study of Monkey crash reproducibility used six open-source apps, 6,000 test cases, and 56 unique crash bugs; it replayed each bug 200 times. Only 36.6% of replays reproduced the crash bugs, and the researchers identified Injection Failure, Event Ambiguity, Data Loading, Widget Loading, and Dynamic Content as five causes of failed reproduction. Understanding the Reproducibility Issues of Monkey for GUI Testing
For your workflow, that means a Monkey-found failure is a lead that needs triage. Capture the relevant evidence, establish whether you can reproduce the behavior, and narrow the triggering conditions before treating it as a stable regression candidate. The 36.6% result belongs to that 2023 study’s apps and replay design; it is not a general reproduction rate for every Android application.
Broad exploration has blind spots
Random GUI exploration can also spend too much time in loops or fail to reach activities whose entry points are concealed. A 2024 preprint describing Delm, a deep-link-integrated Android exploration approach, identifies both limitations. In that paper’s experiments, Delm reported 27.2% activity coverage, 21.13% method coverage, and 23.81% crash detection; those are Delm’s reported results, not performance guarantees for Android Monkey. Delm preprint
This is the practical boundary of monkey testing: it is excellent for expanding the set of states you inspect, not for proving that you inspected every important state. If a critical flow is hard to enter or the tool keeps revisiting a small set of screens, broad exploration needs a more targeted companion technique.
What is gorilla testing?
Gorilla testing is intensive testing of a deliberately selected feature, module, or risk area. Instead of asking the app to wander widely, you choose the area most likely to cause release risk and keep exercising it with repeated attention.
Practitioner guidance consistently describes the process as focused and repetitive. Testsigma’s 2026 guide recommends selecting a module, preparing inputs, running repeated cycles, documenting anomalies, analysing results, retesting, and bringing useful findings into regression work. Testsigma’s gorilla-testing guide TestRail likewise describes gorilla testing as focused, intensive testing of critical modules through repeated, rigorous stress. TestRail’s guide
Those are vendor guides, not controlled effectiveness studies. Their value here is that they make the working process explicit: gorilla testing is defined more by concentrated scope and repeat pressure than by a single required tool or input generator.
Focused does not always mean scripted
Pendo’s 2021 engineering case study adds an important qualification. Pendo describes gorilla testing as rigorously testing a feature in random ways to try to break it, then reports using the approach on a permissions-code change. In that exercise, Pendo reported three high-severity issues and seven lower-severity issues; those findings are results from Pendo’s own exercise, not a benchmark for every team. Pendo’s gorilla-testing case study
That account resolves an apparent contradiction in the terminology. You can select a feature deliberately, define an observation window, repeat the session, and document findings while still using unpredictable interactions within that feature. Gorilla testing is focused at the level of scope; its individual inputs may be structured, varied, or random.
Compare the two techniques by the decision you face
Monkey testing and gorilla testing can both feel exploratory, but they produce different signals. Choosing well starts with the breadth of the question, not with a belief that one technique is more serious than the other.
Choose monkey testing for unknown failure surfaces
Choose monkey testing when you need to discover where an app behaves unexpectedly and you do not yet have a single feature to investigate. It is particularly useful when a release has many possible navigation paths, when recent changes may interact in unclear ways, or when you need a broad robustness pass before prioritising deeper work.
The trade-off is diagnosis. Random exploration can produce an event sequence that is difficult to replay, and the 2023 reproducibility study shows why you should reserve time for triage rather than equating a generated crash with a confirmed regression. Broad discovery without follow-up creates noise; broad discovery with disciplined investigation creates a queue of concrete risks to assess.
Monkey testing is also a poor fit when your real question is narrow from the outset. If a payment confirmation, permissions change, login handoff, or account-recovery path is already the concern, a wide application sweep can consume effort without applying enough pressure to the feature you actually need to understand.
Choose gorilla testing for concentrated feature risk
Choose gorilla testing when you can name the area that deserves scrutiny. A recently changed checkout, a permission boundary, a complex onboarding branch, or a feature with high business impact gives you a clear target for repeated and varied interaction.
The advantage is that you can observe the feature closely, vary conditions deliberately, and follow a finding through retest and regression verification. You are not attempting to cover the whole app. You are trying to learn how one area fails, under what conditions it fails, and whether the failure returns after a fix.
The trade-off is scope. A focused session cannot reveal every unrelated weakness elsewhere in the product. If you choose the wrong target, execute too narrowly, or skip the wider exploration that might have exposed another risky area, gorilla testing can give you confidence in one feature while leaving the rest of the app largely unexamined.
Why the terminology causes confusion
There is no single standards-body definition that settles every use of “gorilla testing.” Vendor and practitioner sources generally describe a focused, methodical, and repeated process, while Pendo’s first-hand account demonstrates that random interactions may still be used within the selected feature.
Treating one description as right and the other as wrong misses the useful distinction. Separate the session design from the input style. Your target selection, notes, retest plan, and exit criteria can be deliberate even if some of the interactions you use to pressure the target are intentionally unpredictable.
You may also encounter inconsistent spelling and origin stories around the term. Pendo says the name is believed to come from an American Tourister advertisement involving a gorilla and luggage, but that is a reported belief rather than confirmed etymology. Pendo’s case study
Use monkey testing and gorilla testing in sequence
You do not need to treat the techniques as mutually exclusive. When you need both broad discovery and focused investigation, use a sequence that gives each technique a distinct job:
Run monkey testing for broad discovery. Look for crashes, odd states, and navigation or robustness failures across a wider surface.
Triage the output. Preserve the conditions around meaningful failures and test whether you can reproduce them before escalating them as stable defects.
Select a high-risk target. Use the triage results, recent code changes, and release-critical flows to choose the feature that needs concentrated attention.
Run a gorilla-testing session. Apply repeated and varied inputs inside that bounded area, observe the results, and document anomalies.
Add verified findings to regression coverage. Once you understand the failure and its expected behavior, include a structured check so a future release can detect its return.
This is a practical decision framework, not a formally validated testing lifecycle. Its logic is straightforward: monkey testing expands your view of possible failure states, while gorilla testing helps you investigate the area that matters most after you have a reason to focus.
If you are deciding where this sits alongside other unscripted work, this guide to ad hoc testing and when unstructured testing is useful provides broader context. Ad hoc testing is not a substitute label for either technique: monkey testing is defined by broad random or pseudo-random exploration, while gorilla testing is defined by concentrated pressure on a selected target.
What the evidence can and cannot support
The research base is uneven. Monkey testing has empirical Android research on runtime, crashes, coverage, reproducibility, and GUI exploration limits. Gorilla testing is supported primarily by practitioner descriptions and a first-party case study rather than a controlled body of head-to-head research.
No source cited here provides a same-application, same-time experiment that compares monkey testing and gorilla testing on defect-finding rate, coverage, cost, or return on effort. You should not infer that monkey testing is more effective simply because it has more published measurement, and you should not assume gorilla testing makes every finding reproducible because its scope is focused.
No first-party Quash data exists to measure the relative effectiveness of monkey testing versus gorilla testing. Establishing a definitive comparative benchmark would require a controlled, same-application experiment measuring defect-finding rate, coverage, and return on effort across a standardized test set—data that does not currently exist in the public record.
That evidence gap should shape your expectations. Use Monkey research to understand what broad Android exploration has shown in specific study settings. Use gorilla testing as a disciplined practical method when your release risk is concentrated in an identifiable feature, and judge its value through the findings and follow-up your own testing produces.
Verdict
Use monkey testing when you need breadth: you are looking for unexpected states, crashes, and robustness failures across an app whose weak points are not yet clear. Use gorilla testing when you need depth: you have identified a feature that is high risk, recently changed, or too important to test lightly.
For a high-risk release, begin with broad discovery, triage what you find, then apply focused pressure where the evidence points. Your decision is not which technique wins. It is whether your next testing session needs a wider search for failure or a deeper understanding of one critical area.
Continue reading
More articles from the Quash editorial desk.