Mocking vs Stubbing in Testing: What’s the Difference?
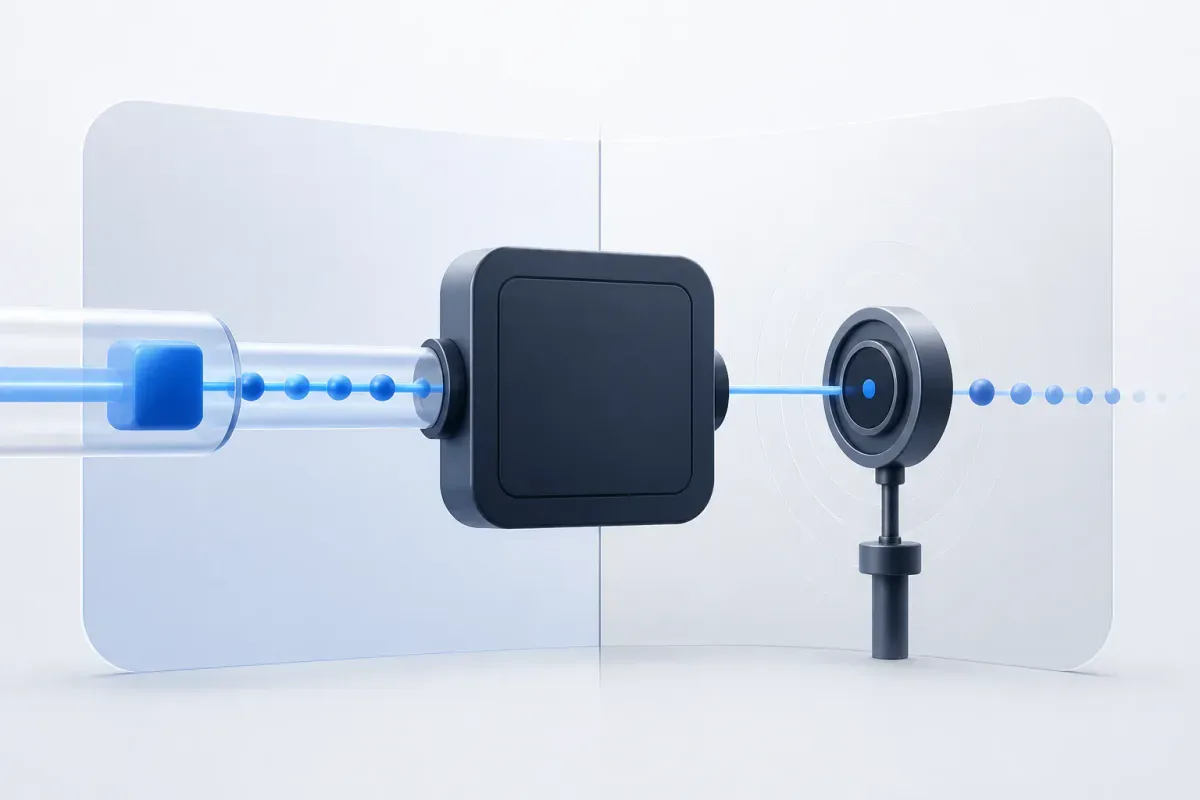
Your test needs a user record, but the database is slow. Or your code must send an activation email, and calling the email provider would make a unit test unreliable. The situations look similar until you ask what the test must prove: did your code produce the right result, or did it perform a required interaction?
The short answer: stubbing supplies a controlled response from a dependency; mocking, in the classic sense, verifies a meaningful interaction with a dependency. Both are test doubles, and the same framework object can do either job. The useful choice is not the class name your library gives it. It is the evidence your test needs.
Mocking vs stubbing at a glance
Question | Prefer a stub when… | Prefer mock-style verification when… |
What must you control? | A dependency response: a record, empty result, exception, or timeout | An interaction that is itself required behavior |
What does your main assertion inspect? | Your unit’s returned result, state, or visible outcome | A required call, argument, count, or meaningful side effect |
Example | A repository returns a known user so activation logic can run | A notification service must receive one activation message |
Main risk | A canned response drifts from the real contract | The test becomes coupled to incidental call structure |
First question to ask | “What input or failure must I create?” | “Which interaction is actually a requirement?” |
This is a working convention, not a universal vocabulary rule. Gerard Meszaros’s test-double taxonomy notes that terminology is confusing and inconsistent across authors and tools. The convention remains useful because it describes the role a replacement plays in a particular test.
Get the Mobile Testing Playbook Used by 800+ QA Teams
Discover 50+ battle-tested strategies to catch critical bugs before production and ship 5-star apps faster.
What is stubbing?
A stub replaces a collaborator so your code receives a controlled answer. You use it to create the precondition needed for the behavior you want to examine: a known record, an empty collection, an error, a timeout, or a boundary value.
Imagine that activate() needs a user from a repository. You want to test activation behavior, not a database query.
Here, repository.findUser() is setup. The important evidence is the result from service.activate(). If you later replace the repository implementation without changing activation behavior, this test should normally continue to pass.
Stubs are especially useful for hard-to-create failure paths. You can make a payment gateway return a decline or make an HTTP client throw a timeout without waiting for a real outage. But a controlled answer is valuable only when it still represents a meaningful version of the dependency’s contract. A stale payload can leave you with a green test and a broken integration.
When a stub is the right fit
Use a stub when you need to:
supply scenario data that a dependency normally returns;
reach a branch that would otherwise require costly or fragile setup;
simulate a documented failure response, exception, or timeout; or
keep the assertion focused on your unit’s state, return value, or observable output.
Name the behavior rather than the collaborator mechanics. activates_an_existing_inactive_user says what must remain true. calls_find_user_once records one implementation route that may not matter to the requirement.
What is mocking?
In the classic vocabulary, a mock supports behavior verification: you configure or observe an expected interaction and assert that it occurred. Use mock-style verification when the interaction is part of the requirement, rather than merely an internal route to a result.
Consider the same activation flow. If sending an activation message is a promised outcome, your test needs evidence that the notification was requested.
The interaction matters because “send the activation message” is behavior another system or the user relies on. Checking only result.status == "active" could miss a regression that silently removes the notification.
Martin Fowler distinguishes state verification from behavior verification. He also separates that distinction from the broader classical-versus-mockist testing debate. A role label is not a complete testing philosophy.
When mock-style verification is the right fit
Mock-style verification fits when you need to prove that your code:
emitted a required domain event;
sent a required notification or command;
made a required write at an external boundary;
passed contractually important information; or
performed calls in a specific order because that order is itself required.
The word required matters. A mock assertion becomes brittle when it freezes an implementation detail you should be free to refactor. If batching two requests or moving a helper call would not change promised behavior, that call is usually a poor candidate for verification.
The key difference is the evidence your test needs
A framework class name does not determine whether you are mocking or stubbing. A Mock object that only returns User(...) does a stub’s practical job. The same object becomes part of a mock-style test when your assertion checks send(...), call count, arguments, or order.
Use this purpose-first rule:
Stub: “Give me this response so I can exercise the behavior.”
Mock-style verification: “Show me this required interaction occurred.”
That rule resolves many naming arguments before they start. In review, first identify the scenario input, then identify the behavior under test, then ask whether an interaction assertion represents an actual requirement.
The distinction is not “stubs are for reads and mocks are for writes.” Vladimir Khorikov argues that incoming data dependencies commonly suit stubbing while outgoing side effects commonly merit mocks. That is useful practitioner guidance, not a standard that overrides your system’s requirements.
How do stubs, mocks, spies, fakes, and dummies differ?
Test double is the umbrella term for a replacement used in a test. The roles below are a practical map, based on Meszaros’s terminology, rather than a demand that every library expose five different classes.
Role | What it does in your test | Typical evidence you inspect |
Dummy | Satisfies a required parameter but is not used | Usually none |
Stub | Supplies controlled answers or indirect inputs | Your unit’s result or the path reached |
Spy | Records calls or arguments for later inspection | The recorded interaction after execution |
Mock | Represents expected interactions | Interaction or behavior verification |
Fake | Supplies a lightweight working implementation | Your unit’s behavior with a more realistic collaborator |
A spy and a mock can look similar because both may involve checking calls. The practical difference is often when and how the interaction expectation is expressed. More importantly, neither label answers the central question: are you controlling an input, or proving a meaningful collaboration?
Should you use a real dependency or a fake instead?
Mocking versus stubbing is not the only decision. Before replacing a dependency, ask whether a real implementation provides better confidence at an acceptable cost.
Google’s test-fidelity guidance defines fidelity as how closely test behavior resembles production behavior. It recommends trying the real implementation first, using a fake when the real dependency is unsuitable, and using a mock when neither is suitable. Slowness, nondeterminism, and difficult setup can make a real dependency unsuitable.
Use this sequence:
Can you run the real dependency quickly and deterministically? If yes, it may be the clearest choice.
Can you build or reuse a lightweight fake? An in-memory repository can preserve more behavior than a few canned replies, but it needs maintenance.
Do you need a particular input or failure to isolate the scenario? Use a stub.
Is an interaction itself a requirement? Add narrow mock-style verification for that interaction.
For example, a small in-memory rules engine can be a better collaborator than a stub when your test needs several realistic rule combinations. A remote email provider is usually a poor unit-test dependency; a stub or mock gives you control without contacting it.
Avoid the common failure modes
The most useful distinction between mocking and stubbing is the one that prevents a low-value test.
Calling every double a mock
If you call every replacement a mock, you lose the reason it exists. In code review, say whether the double provides scenario input, records an interaction, or verifies a requirement. That is clearer than arguing over a library’s class name.
Verifying every call
Assertions against every collaborator call turn a test into a transcript of today’s implementation. Keep verification for meaningful side effects and required arguments. Let state or output assertions carry the rest of the behavior.
A 2025 empirical study of 4,652 test cases from 11 open-source Java projects found that 1,917 test cases (41%) contained at least one mock assertion, while 9% of method invocations on test doubles were verified on average. That bounded sample does not prescribe a rule for every language, but it supports selective rather than blanket interaction verification.
Stubbing without checking the contract elsewhere
A stub can keep returning a payload after the real service has changed its schema or semantics. Preserve some integration or contract coverage where the collaboration matters, or prefer a fake or real implementation when feasible. If you need a refresher on where those combined checks fit, Quash’s integration testing guide covers the layer where components run together.
Mocking a simple deterministic collaborator
Replacing a fast, stable, in-process collaborator can add setup noise and reduce fidelity without buying useful isolation. Run the real implementation when it remains practical.
Using the wrong evidence type
If your requirement says “publish one event,” a return-value assertion alone may not prove enough. If your requirement says “calculate the correct total,” interaction assertions alone may miss the actual defect. Match the assertion to the behavior you promised.
Why stubs and drivers are not the same thing
A driver and a stub sit on opposite sides of the unit under test. A driver is caller-side scaffolding: it invokes the unit. A stub is callee-side scaffolding: it replaces something the unit invokes.
Old Dominion University’s unit-testing material states this caller/callee distinction directly. A Purdue-hosted reproduction of Glenford Myers’s testing chapter likewise explains that module testing can require special drivers and one or more stubs.
That difference matters in integration work. Bottom-up testing can use drivers while higher-level callers are unavailable. Top-down testing can use stubs while lower-level collaborators are unavailable. This direction-of-control distinction is separate from mock-style verification: a stub does not become a mock because it appears in an integration test, and a driver is not a kind of mock.
How framework terminology changes
Tool vocabulary can make a clear testing decision look muddy. State what the double does instead of assuming a tool’s word means the same thing everywhere.
Python: The standard-library unittest.mock describes replacements for parts of the system under test and provides assertions about how they were used. A Python
Mockconfigured only with a return value can therefore serve a stub role;assert_called_once_with()makes the interaction part of your evidence.Mockito: The Mockito 5.23.0 API explicitly covers mock creation, verification, and stubbing. The library supports both activities, so
mock()in setup does not itself reveal the test’s intent.Node.js: Node’s official mocking guide defines stub and mock in its own way, then says the distinction is unimportant for that document and uses “mocks” broadly. Follow its local convention when reading its API, but do not export it as a universal definition.
.NET: Microsoft’s unit-testing best-practices guidance cautions that testing literature and tools use terms such as fake, stub, and mock inconsistently. In your codebase, a short testing convention is more useful than enforcing a word each library uses differently.
What the available evidence does not settle
No first-party Quash telemetry, customer data, recurring defect pattern, or completed experiment currently compares the effectiveness of mocks, stubs, fakes, and real dependencies. Public guidance can explain the roles and trade-offs, but it cannot establish which choice detects more defects in your specific codebase.
A useful missing study would run comparable real-world mobile test suites with deliberately chosen doubles, then measure defect-detection rates, false failures, maintenance time, and time to diagnose failures. Until that controlled evidence exists, choose from the requirement and fidelity of the dependency rather than claiming that one double type wins everywhere.
Verdict: mocking vs stubbing
Use a stub when a controlled dependency response is setup for the scenario you need to test. Use mock-style verification when an interaction is a meaningful requirement and you need evidence that it happened.
Before choosing either, try the real dependency if it is fast, deterministic, and practical. Use a fake when it preserves useful behavior at manageable maintenance cost. Then choose the least artificial double that lets your test prove the requirement: controlled input for a stub, targeted interaction evidence for a mock.
For the adjacent basics of test isolation and unit scope, read Quash’s simple guide to unit testing.
Continue reading
More articles from the Quash editorial desk.