Blue-Green Deployment vs Canary Release: How to Test Both (2026)
A deployment can pass every pre-release check and still fail when traffic moves, sessions cross versions, or a database change has to be undone. The rollout method you choose determines which of those risks you can observe before every user is affected.
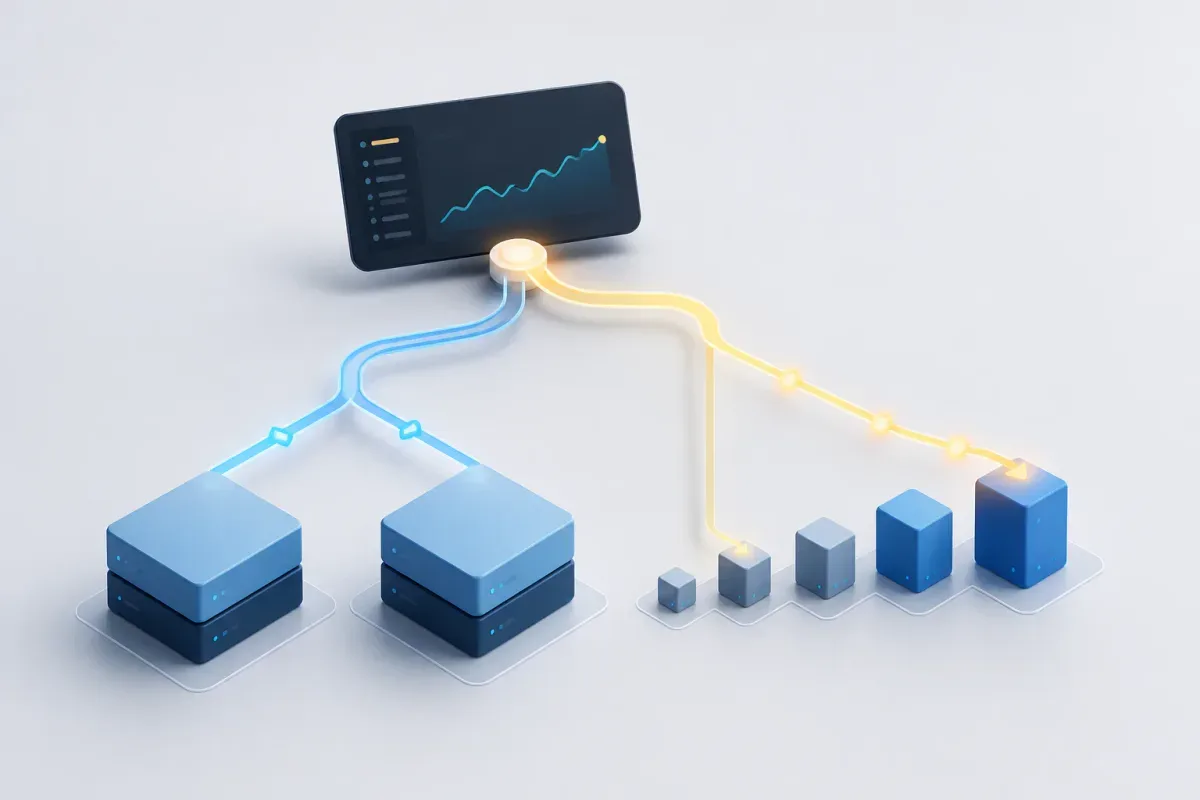
The short answer: blue-green deployment runs a new release in a parallel, production-capable environment before switching traffic; a canary release sends the new release to a limited, time-bound portion of production traffic and evaluates it against a control or baseline. Blue-green is strongest for validating a complete replacement and reversing a cutover. Canary is strongest for gathering comparative production evidence gradually. You can also combine them: validate a green environment first, then expose it progressively.
Blue-green deployment vs canary release at a glance
Dimension | Blue-green deployment | Canary release |
Core model | Run a parallel environment, then switch traffic from blue to green | Send a new version to a limited traffic slice before broader release |
Primary question | Can the replacement environment take over and reverse safely? | Does the new version behave acceptably against a control under real traffic? |
Best evidence | Environment validation, cutover rehearsal, and rollback rehearsal | Version- or cohort-partitioned metrics and staged exposure results |
Initial user exposure | Often none until cutover, unless you add a progressive routing phase | A defined subset of production traffic |
Rollback action | Route traffic back to the retained blue environment | Halt or reverse the rollout and return traffic to the stable version |
Main dependency | Environment parity, routing, capacity, and version compatibility | Traffic segmentation, instrumentation, baseline quality, and decision gates |
Common failure mode | The app works in green but the traffic or state transition fails | The analysis misses or misreads a small, noisy, or unrepresentative signal |
Best fit | You need a complete pre-cutover environment and fast reversal | You need gradual, real-user evidence before full exposure |
This is a practical comparison, not a claim that one method always wins. The useful distinction is an editorial synthesis of the cited guidance: blue-green chiefly describes where the new release runs, while canary chiefly describes how much traffic sees it and how you evaluate it.
Get the Mobile Testing Playbook Used by 800+ QA Teams
Discover 50+ battle-tested strategies to catch critical bugs before production and ship 5-star apps faster.
What blue-green deployment and canary release each prove
In blue-green deployment, blue serves production while green holds the candidate release. Microsoft describes a safe-deployment pattern in which a green pool is tested internally before traffic is routed to it; AWS similarly recommends deploying updated immutable resources in parallel, validating them automatically, then shifting traffic. Microsoft’s safe-deployment guidance and the AWS Reliability Pillar support that sequence.
That structure gives you strong evidence about the replacement environment: its artifact, configuration, dependencies, capacity, health checks, and its ability to accept traffic. It does not automatically prove that the switch itself, or a stateful rollback, is safe.
Canarying is a partial, time-limited deployment plus evaluation. Google SRE describes the changed portion as the canary and the remaining fleet as a control, with production traffic able to reveal defects that artificial tests may miss. Google SRE’s canary guidance is why a canary should complement pre-release tests rather than replace them.
Canarying gives you comparative production evidence. It does not make an arbitrary small percentage representative, and it does not help if your metrics cannot distinguish the candidate version from the baseline.
How to test blue-green deployment before cutover
The following checklist is a recommended testing framework synthesized from AWS and Microsoft guidance. It is not a universal standard or a vendor-prescribed sequence.
Verify that green is a production-capable environment
Confirm that green contains the intended artifact, version, and runtime configuration. Then compare the behavior-changing parts of blue and green: secrets, service discovery, routes, dependencies, capacity limits, feature configuration, and required state.
A parallel environment is only useful as a rollback target or replacement if it can actually carry the relevant production load. Test the capacity assumptions that matter to your service rather than assuming that a healthy startup probe proves production readiness.
Run critical checks against green
Before switching traffic, run checks that answer whether green can serve the release-critical experience:
Startup and readiness checks for the application and dependent services.
Smoke tests for obvious breakage.
Critical-path tests for the workflows that would block users or revenue if they failed.
Integration checks for services, APIs, identity, payments, messaging, or other dependencies that the release changes.
Compatibility checks for old and new application versions that may coexist during the transition.
Security or policy checks required by your own release process.
Automatic validation before traffic shifting is part of AWS’s immutable-infrastructure guidance. Health-gated stages are central to Microsoft’s safe-deployment guidance. The exact test set should follow your service’s failure modes, not a generic checklist.
Test the traffic switch as its own release event
A green environment can pass functional checks and still fail when traffic moves. Exercise the mechanism that will switch production traffic, including load-balancer or routing rules, service discovery, DNS behavior where relevant, session affinity, cache invalidation, queues, scheduled work, and long-running requests.
Treat a successful request after the switch as a smoke signal, not final proof. Observe error rate, latency, saturation, workflow completion, and deployment state by environment so you can tell whether green is healthy after exposure.
Rehearse reversal and verify data after rollback
Keep blue viable until the agreed rollback period ends. Then test the backward path deliberately: route traffic back to blue, confirm the critical workflows, and verify that state created or changed during the forward transition remains valid.
AWS’s rollback-safety guidance makes the important distinction: a release can work in either endpoint state but fail during upgrade or downgrade. Your test plan needs to cover coexistence, forward deployment, and rollback in a production-representative environment.
How to test a canary release before you promote it
Canary testing evaluates two things at once: the candidate release and the system that decides whether to promote it. Google Cloud Deploy documents canary rollout phases that split traffic between an existing version and a new version before the final stable phase. Google Cloud’s canary documentation describes the platform-specific mechanism; your gates and metrics remain your responsibility.
Define the cohort, control, metrics, and observation window
Before the first canary request, define four items:
Cohort: which users, regions, tenants, devices, or requests can receive the candidate.
Control or baseline: what you will compare it with.
Success signals: the version-partitioned measures that matter, such as error rate, latency, crashes, saturation, and critical workflow completion.
Observation window: how long you need to wait before a relevant failure would reasonably appear.
A small cohort is not inherently a useful cohort. If a release changes checkout, for example, a canary consisting only of read-only traffic cannot provide meaningful evidence about checkout behavior.
Make the canary visible in your telemetry
Do not rely only on aggregate production health. A small canary regression can disappear inside a fleet-wide average. Tag or partition metrics by version, cohort, environment, or another stable release identifier so you can compare the candidate with the control.
Microsoft advises measuring bake times in hours and days rather than minutes as a general operational principle, not as a universal duration. Your observation window should cover the usage pattern and failure-detection latency that matter for the release. A background reconciliation failure may need longer observation than an HTTP routing error.
Validate the analysis system itself
A canary decision system can be wrong even when the release is fine. Google and Waze recommend validating canary analysis with known-good and known-bad cases, as well as an A-A test in which both sides run the same version. Their canary-analysis guidance supports these checks as a way to test the comparison system, not just the code being deployed.
Where it is safe to do so, confirm that a deliberately faulty or previously known-bad build triggers the gate. Confirm that a known-good build does not create false alarms. Then use an A-A run to reveal baseline noise or analysis bias before it controls a high-stakes rollout.
Predefine promote, pause, rollback, and inconclusive outcomes
Write the decision logic before exposure begins. A healthy canary can promote; an unhealthy canary rolls back; an inconclusive canary pauses while you gather enough evidence or investigate instrumentation.
AWS lists fault rate, latency, CPU, memory, disk, and log errors as examples of rollback-alarm inputs and recommends an observation period after deployment. Those are examples, not a universal alarm set. AWS DevOps Guidance also emphasizes retaining a known-good artifact for recovery.
Blue-green deployment vs canary release: the operational trade-offs
Environment capacity and isolation
Blue-green requires a parallel environment capable of doing the job you expect green to do. That can simplify pre-cutover validation and speed reversal, but it makes environment parity and capacity planning non-negotiable. The infrastructure cost is workload- and platform-dependent; no fixed cost multiplier applies to every blue-green deployment.
Canary can require less duplicate capacity at the start because only part of production receives the candidate. Its trade-off is more dependence on reliable segmentation and observability. If you cannot identify which requests reached which version, you cannot confidently interpret the canary.
Traffic control and production feedback
Blue-green usually gives you a decisive switch: traffic is routed to blue or green. That is valuable when a clean full cutover and fast reversal matter most.
Canary gives you an explicit exposure ramp. It is valuable when you need production evidence before committing the whole population. AWS documents a small initial increment followed by a later increment or linear expansion; the percentage and phase count should be chosen for your system, not copied as a universal recipe from AWS’s canary deployment overview.
Rollback speed and rollback safety
Blue-green can reverse rapidly when the old environment remains healthy and routing is under your control. That strength disappears if a data or configuration change leaves blue unable to serve safely.
A canary can limit blast radius because only a defined cohort sees the candidate initially. But its rollback safety depends on timely detection, a working traffic-control path, and old/new version compatibility. In both models, rehearse the recovery path instead of treating it as a button you have never pressed.
Sessions, background work, APIs, and schemas
Both approaches become harder when state crosses a version boundary. Sessions, caches, queues, long-running workers, scheduled jobs, APIs, and schemas can all create mixed-version behavior.
HashiCorp warns that stateful workloads need additional work under blue-green, canary, and rolling strategies. The peer-reviewed QuantumDB research record also addresses the practical difficulty of evolving a SQL schema without taking a web service offline. Read HashiCorp’s deployment-strategy guidance and the TU Delft record for the QuantumDB paper as support for treating state compatibility as a separate design and test concern.
Your migration plan might use an expand-and-contract approach or another documented compatibility strategy. The important test is that old and new versions can coexist through both promotion and reversal; no single database pattern fits every system.
Combine blue-green deployment and canary release when both risks matter
You do not have to choose these patterns as opposing camps. A blue-green canary hybrid uses a complete green environment for isolation, then routes a controlled share of production traffic to green before a full cutover.
Use this sequence:
Deploy the candidate to a production-capable green environment.
Validate green internally with smoke, critical-path, integration, and compatibility checks.
Route a defined canary cohort to green while blue remains the control or stable baseline.
Compare version- and cohort-partitioned health signals during a defined observation window.
Pause or route traffic back to blue when a predeclared gate fails.
Complete the cutover only after the evidence is sufficient, while retaining blue for the agreed rollback period.
Microsoft documents the component pattern of internally validating a green pool before limited traffic routing, while Google SRE documents the comparison value of a canary and control. The combined two-axis framing is this article’s synthesis of those mechanisms, not a named industry standard.
Use this rollout test checklist for either strategy
Use this as a release-readiness checklist, then add the blue-green or canary checks that fit your rollout shape:
Confirm artifact identity: verify the build, version, configuration, and dependencies you intend to ship.
Check environment and state parity: identify differences in settings, secrets, routes, capacity, caches, queues, and required data.
Run release-critical checks: cover startup, readiness, smoke tests, and the workflows that must work after deployment.
Prove compatibility: test APIs, schemas, and data behavior while old and new versions coexist.
Exercise routing: test the traffic switch or cohort rules, session behavior, background work, and long-running requests.
Partition observability: distinguish blue from green or candidate from control in metrics, logs, traces, crashes, and workflow outcomes.
Set gates in advance: define promotion, pause, rollback, and inconclusive outcomes before exposure.
Choose a meaningful bake window: wait long enough for the relevant usage pattern and failure mode to appear.
Rehearse rollback: test the backward transition and data integrity after reversal.
Keep a recovery plan current: maintain the known-good artifact, owner responsibilities, and contingency steps.
CISA’s 2024 safe-software-deployment guidance similarly emphasizes robust testing, measurement, maintained playbooks, and contingency planning. For the pipeline context around these checks, see Quash’s CD test strategies guide.
Which rollout strategy should you choose?
Choose blue-green deployment when you need a production-capable replacement environment, a clear traffic switch, and a fast route back to the prior environment. It fits when the hardest problem is proving that a complete environment can take over safely.
Choose canary release when gradual real-user evidence is more valuable than an immediate fleet-wide switch, and you can segment traffic and compare trustworthy version-level signals. It fits when the hardest problem is learning how the candidate behaves under real production conditions.
Choose a blue-green canary hybrid when you need both: pre-cutover isolation in green and a measured production ramp before full cutover.
Do not make the decision on deployment terminology alone. Make it on the risks you can actually control: rollback urgency, parallel-environment capacity, traffic-routing precision, observability maturity, state compatibility, and whether a representative cohort can provide the evidence you need.
Conclusion
Blue-green deployment and canary release solve different release risks. Blue-green helps you validate and reverse a complete environment change. Canary helps you evaluate controlled production exposure. Your safest choice is the one whose test plan covers the transition—not only the destination—and whose evidence is strong enough to tell you when to stop.
Continue reading
More articles from the Quash editorial desk.