Mutation Testing: What It Is and Why It Matters (2026)
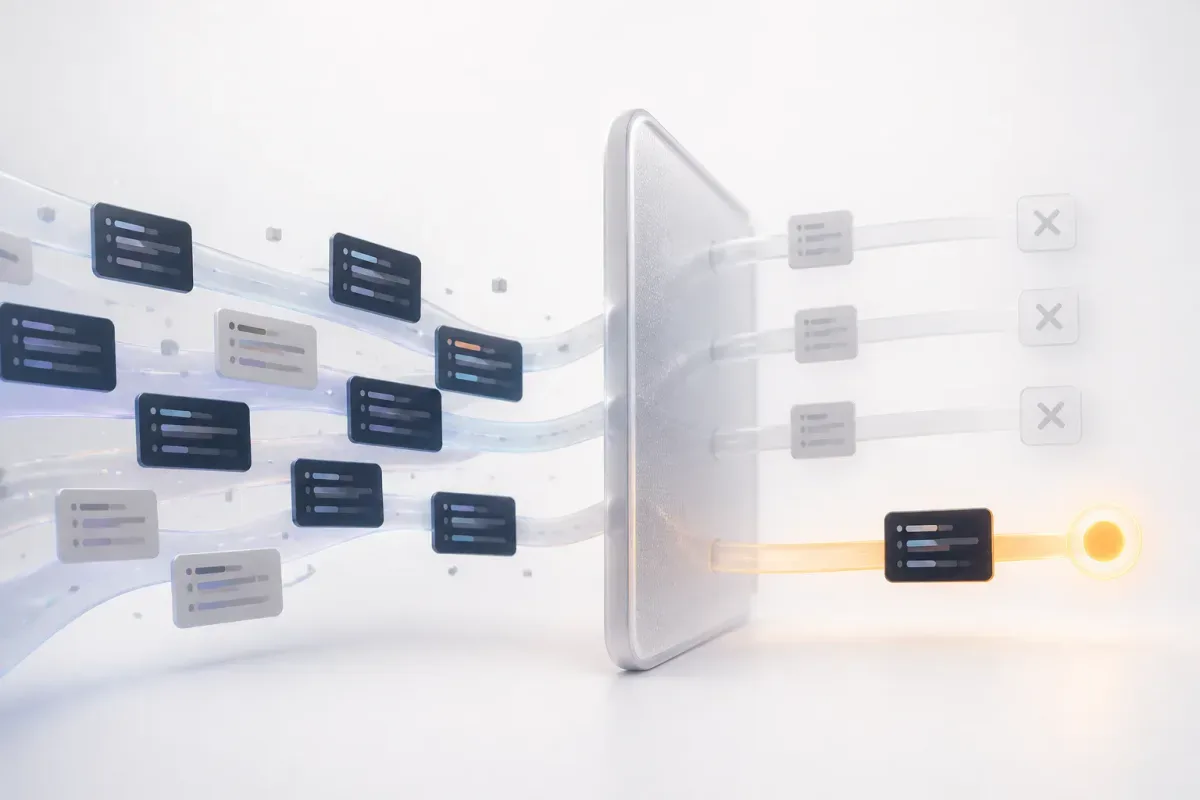
A suite can report 90% line coverage and still let a regression through, because the tests ran the code without checking what happens when the code is wrong. Mutation testing measures that gap. It seeds small, deliberate faults into your program, runs your tests against each one, and counts how many the tests catch. The share caught is the mutation score.
The evidence on whether that score tracks real bugs is split, and both halves are citable. A 2014 study found mutant detection correlated with real fault detection beyond coverage. A 2018 study attributed that kind of correlation to test-suite size. Every figure below carries its study and year, and none of them was measured in 2026.
Key mutation testing statistics
357 real faults in 5 open-source applications (321,000 lines of code): mutant detection correlated with real fault detection independently of code coverage. Just et al., FSE 2014, author-hosted abstract.
Two datasets, CoreBench and Defects4J (large C and Java programs with real faults): the correlation was attributed to the confounding effect of test-suite size. Papadakis et al., 2018, institutional record of the paper.
More than 24,000 developers on more than 1,000 projects at Google: a code-review-based approach produced orders of magnitude fewer mutants. Petrović et al., IEEE TSE 2021, arXiv abstract.
Almost 17 million mutants and 760,000 changes evaluated, 2 million mutants surfaced in code review. Same study, 2021, full text.
Developer-judged productive mutants rose from 15% to 89% over six years of feedback from more than 20,000 Google developers. This is developer judgment on surfaced mutants that received feedback, not tests killed or bugs found. Same study, 2021.
82% of all surfaced mutants with feedback were labeled productive, with productivity rising from 80% to 89% since the service began. Same study, 2021.
Median of 7 mutants per changelist, against 820 for traditional mutagenesis. A count of generated mutants, not a runtime saving. Same study, 2021.
87.5% of generated mutants killed by the initial test suite. The paper states this is not the traditional mutation score, because its mutagenesis is probabilistic and generates only a subset. Same study, 2021.
13 minutes for extreme mutation testing, against 37 minutes for PIT's seven default mutators, on one semiconductor project with 11,424 unit tests. Betka and Wagner, 2021, full text.
291 of 2,041 methods (14%) pseudo-tested: fully covered but functionally unverified. Same project and study, 2021.
262 types of Android faults in 14 categories, from manual analysis of 2,023 software artifacts. Linares-Vásquez et al., 2017, arXiv abstract.
38 Android mutation operators identified, 35 implemented in a research framework. Same study, 2017.
Get the Mobile Testing Playbook Used by 800+ QA Teams
Discover 50+ battle-tested strategies to catch critical bugs before production and ship 5-star apps faster.
How does mutation testing work?
Mutation testing is a fault-based technique. A tool creates mutants: copies of your program with one small syntactic change each, such as flipping a comparison or deleting a statement. The formal yardstick is the "mutation adequacy score", which measures how well a test set detects faults (Mutation Testing Repository).
The loop has four steps:
The tool generates mutants from source or compiled code.
It runs your test suite against each mutant separately.
If a test fails, the mutant is killed. If every test passes, the mutant survived.
The mutation score is the share of mutants killed.
PIT, the Java tool, describes it in one sentence: "if your tests fail then the mutation is killed, if your tests pass then the mutation lived" (PIT). Stryker documents the same mechanics: the higher the percentage of mutants killed, the more effective your tests are (Stryker docs). If you want the wider white-box context, our white-box testing guide places mutation testing among the other code-aware techniques.
The idea is older than the tools. The Mutation Testing Repository says it "can be traced back to 1971 in a student paper by Richard Lipton", with the field's foundations in late-1970s papers by DeMillo et al. and Hamlet. That page is a secondary overview, so treat the history as reported by the repository, not as a reading of the original papers.
What does mutation testing measure that coverage does not?
Coverage tools report which code ran. Mutation testing asks whether a change to that code would be noticed. PIT, which makes a mutation tool, states the limit of coverage plainly:
"Traditional test coverage (i.e line, statement, branch, etc.) measures only which code is executed by your tests. It does not check that your tests are actually able to detect faults in the executed code. It is therefore only able to identify code that is definitely not tested." — PIT
Stryker makes the same point from the practitioner side, asking when you last saw a test without an assertion, written only to raise coverage (Stryker docs). Line and branch coverage also say nothing about device state, network conditions or timing, which matters for mobile apps. If you are choosing coverage tooling first, our code coverage tools comparison covers what each one reports.
Here is an illustrative example. It is not drawn from any dataset or tool run. Suppose your code reads if (retryCount >= maxRetries) and a mutant changes >= to >.
The surviving test taps through the retry flow and asserts only that nothing threw. Coverage records the line as executed. The mutant survives because no assertion notices the change.
The killing test asserts that a retry occurs at exactly
maxRetries. The off-by-one now fails the assertion and the mutant is killed.
Four other outcomes are not a simple kill. A mutant survives as no coverage if no test reaches its line. A timeout counts as detected. A compile or runtime error leaves the score's denominator.
An equivalent mutant behaves identically to the original, so no test can kill it. The next sections define each outcome.
Does a high mutation score track real faults?
The answer depends on which study you read.
The 2014 result: a positive association beyond coverage. Just, Jalali, Inozemtseva, Ernst, Holmes and Fraser report that their experiments "used 357 real faults in 5 open-source applications that comprise a total of 321,000 lines of code", with both developer-written and automatically generated test suites. They found "a statistically significant correlation between mutant detection and real fault detection, independently of code coverage" (author-hosted abstract).
The 2018 result: the association is confounded by suite size. Papadakis, Yoo, Shin and Bae studied CoreBench and Defects4J, which hold large C and Java programs with real faults. They concluded that "correlations are the results of the confounding effects of the test suite size" (institutional record).
The two studies are not contradictory measurements of one thing. They used different datasets and different controls. The 2014 study asked whether mutant detection adds information beyond coverage. The 2018 study asked whether the correlation survives once suite size is controlled.
The defensible reading is narrow. Mutation score is evidence about how well a suite checks behaviour. It is not a proxy for production reliability, and its value over a well-sized suite is the question the field has argued about since. Neither study shows that mutation testing reduces escaped defects, lowers the cost of quality, or predicts production incidents.
What did six years of tuning at Google show?
Google's deployment is the largest published account of mutation testing inside a development workflow. Petrović, Ivanković, Fraser and Just describe it in "Practical Mutation Testing at Scale" (IEEE Transactions on Software Engineering, 2021; arXiv abstract). Their premise is that traditional whole-codebase mutation does not scale to Google's codebase.
The start was poor. Even after sampling to cut the number of mutants, "developers at Google initially classified 85% of reported mutants as unproductive" (full text). Developer feedback then drove suppression heuristics. Across six years and feedback from more than 20,000 developers, the ratio of productive mutants rose "from 15% to 89%".
Two qualifiers apply. The productivity analysis excludes surfaced mutants with no explicit developer feedback, so 15% to 89% describes developer-judged productivity on mutants that received feedback. And the exact contribution of early suppressions is hard to measure, so the arc is a tuning story, not a controlled causal estimate. The aggregate companion figure is 82% of all surfaced mutants with feedback labeled productive, up from 80% to 89% since launch.
Selection did much of the work. With suppression and one mutant per line, the median changelist received 7 mutants, against 820 under traditional mutagenesis. That counts generated mutants per changelist and says nothing about runtime.
One figure is easy to misread. The paper reports that 87.5% of generated mutants are killed by the initial test suite, then adds that this is not the traditional mutation score, because the mutagenesis is probabilistic and covers only a subset of mutants. Quoted without that caveat, it reads like a Google-wide mutation score. It is not one.
The lesson for you is about cost, not ceiling. Before proposing mutation testing, ask how much triage the first batch of mutants will demand and whether you can tune it down. Google's early ratio was poor and its later one good, and the difference came from maintenance.
Why can "mutation score" mean two different numbers?
Stryker's documentation shows how the score is built. Detected is killed plus timeout. Undetected is survived plus no coverage. Covered is detected plus survived. Valid is detected plus undetected, where valid mutants are those that did not produce a compile or runtime error (Stryker: mutant states and metrics).
From those states Stryker publishes two scores:
Mutation score = detected / valid × 100
Mutation score based on covered code = detected / covered × 100
Timeouts count as detected, on the documented reasoning that a CI build would catch a hang. Runtime and compile errors leave the denominator. So two teams can run the same suite over the same code and each report a correct, different number. Any score you quote should name its denominator. For more on how coverage figures get defined, see our test coverage metrics guide.
Equivalent mutants add a ceiling. Stryker states there is "no definitive way for Stryker to find and ignore them", and that your options are to find them by hand, rewrite the code so they cannot occur, or accept that you won't reach 100% (Stryker: equivalent mutants). That is one tool's limit. A suite with no equivalent mutants has no such ceiling. A surviving mutant calls for triage before it calls for a new test.
PIT takes a different route. It mutates compiled bytecode, which it describes as "generally much faster and easier to incorporate into a build", and designs its operators to "minimise the number of equivalent mutations" (PIT mutation operators). These are the tool author's claims, not an independent benchmark. Measured timings follow in the extreme mutation section.
Why do mobile test suites make this harder?
Most mutation tools were built for general-purpose languages, and their operators reflect that. The strongest published argument for mobile-specific work is "Enabling Mutation Testing for Android Apps" by Linares-Vásquez and colleagues (ESEC/FSE 2017; arXiv abstract). They built a taxonomy of 262 Android fault types in 14 categories from 2,023 artifacts such as bug reports and commits. They identified 38 mutation operators and implemented automated seeding for 35.
Their premise is that mutants generally represent real faults, but effective mutation testing needs "traditional" operators augmented with operators specific to an application domain or technology. That supports three narrow points: language-level operators were not designed for Android's fault classes, domain-specific operators have been argued to be necessary, and a research framework implemented 35 of the 38 operators identified.
It does not rank which Android risks matter most. A taxonomy of reported faults is not a frequency distribution. The study dates from 2017 and covers Android only, and no iOS mutation-testing evidence was located, so do not extend it to iOS.
What is the cheaper way in?
If full mutation testing is too slow for your pipeline, extreme mutation testing is a lighter starting point. Betka and Wagner ran traditional and extreme mutation testing with PIT on "a large software project from the semiconductor industry" with 11,424 unit tests that normally finish in 12 seconds (full text).
Configuration | Mutation score | Killed / total | Survived | Mutators | Tests executed | Time |
Extreme | 85% | 2,297 / 2,706 | 409 | 19 | 597,877 | 13 min |
Traditional (PIT default set) | 73% | 5,813 / 7,989 | 2,176 | 7 | 4,228,169 | 37 min |
Traditional (PIT all mutators) | 70% | 55,515 / 79,350 | 23,835 | 66 | 34,391,374 | 4 h 1 min |
Source: Betka and Wagner, 2021. One project, one machine, one tool. These timings are not a general speed guarantee and not a 2026 benchmark.
The authors summarise: traditional mutation testing with seven default mutators "takes almost three times as long (37 min.) as extreme mutation testing (13 min.), despite having only about a third of the number of mutators."
The same study found 291 pseudo-tested methods, 14% of 2,041. Its analysis of 25 such methods traces them to weak tests with no assertions, incomplete tests and side-effect methods. The authors propose highlighting pseudo-tested code in coverage reports (arXiv abstract).
Its remediation estimates of about 24 hours or seven days rest on a hypothetical five minutes per method. They are arithmetic, not measurements. If you plan to run this in CI, our unit testing in CI/CD guide covers where unit tests sit in the pipeline.
What does this evidence still not tell you?
Four gaps matter before you propose this internally.
Which fault classes break mobile apps first. No published distribution of fault classes surfaced by mutation testing against real mobile apps was located. The Android taxonomy is from 2017 and is not a frequency measure.
Device versus emulator. No paired measurement of mutation-testing outcomes on physical devices and emulators was located. The claim that emulators miss failures is widely made and unmeasured here.
Adoption. This article cites no adoption or satisfaction figure. The 2024 IEEE Transactions on Software Engineering survey of open-source developers, "Mutation Testing in Practice", is the study to consult for that question.
Recency. Every figure here comes from a study between 2014 and 2021. The year in the title marks publication, not measurement.
Quash has no first-party data on this question, so nothing here is a Quash measurement.
Conclusion
Mutation testing answers a question coverage cannot: would your tests notice a small, deliberate change in behaviour? The evidence on whether a high score predicts real fault detection is more mixed than tool documentation suggests, and the 2018 study belongs beside the 2014 result.
Treat the score as a way to find weak assertions, not as a quality guarantee. Pick one module with a history of escaped defects, run a bounded configuration such as extreme mutation testing, and read the survivors. Then decide whether what you learned justifies the triage cost.
Methodology
The article draws on peer-reviewed or conference studies (2014 via its author-hosted abstract, 2018 via its institutional record, and 2017 and 2021 via arXiv), the PIT and Stryker documentation, and the Mutation Testing Repository for history. Tool-vendor statements are attributed to the vendor. Measured timings come only from the 2021 industrial case study.
The 2014 and 2018 studies appear together because they used different datasets and controls and reach different conclusions about the same relationship. Google's daily test volume is reported as more than 500,000,000 in the arXiv version and more than 150,000,000 in Google Research's record of the same paper, so neither figure is used. Figures that appear only in the 2024 adoption survey or in the full text of the 2014 paper are not used; those studies are cited through their abstracts or not at all.
Continue reading
More articles from the Quash editorial desk.